How Tropic verifies every bootloader release with AI


A secure element has to solve its job twice
A secure element’s whole purpose is to resist attackers who have the chip in their hands. As a result, our bootloader firmware is full of deliberate countermeasures including reading values twice, control-flow checkpoints, and alarms that halt processing the instant something looks wrong.
Here’s the catch. Those countermeasures live in our C source, and during development, we can compile and test them on an FPGA board. Our bootloader is compiled once to the actual TROPIC01 chip, with aggressive optimization, and burned into a 16 KB read-only memory (ROM). An optimizing compiler will normally delete a check that appears redundant, which is exactly how our countermeasures are engineered. Present in the source is not the same as present in the silicon. Verifying a release means proving both, and because TROPIC01 is open, we can hand our real firmware to the best AI models available to help, without the confidentiality dilemma a closed vendor faces.
Our approach: AI skills that live in the repo
We did not want a one-off “we asked a chatbot and it looked fine.” Verification has to be reproducible, versioned, and traceable to an exact commit, the same bar as the rest of our release process.
So we built a small set of purpose-made AI skills to aid developers that live inside the firmware repository, under version control, right next to the code they analyze. Every run pins itself to a build hash and writes its output back into the repo, so anyone can re-run it and reproduce the result. Three of them carry the bootloader:
- Static analysis: a security-focused code review across the bootloader, application, and crypto-coprocessor firmware. It rates each finding by whether it’s actually reachable by an attacker over the chip’s external interface, so severity means something, and it carries a curated library of known false-positive patterns so it doesn’t keep re-flagging things we’ve already ruled out.
- Hardening inventory: an audit that walks the source and catalogs every FI/security countermeasure it finds, by type and exact location.
- Hardening cross-check: it takes each countermeasure from the inventory and verifies it against the actual RISC-V disassembly, returning a strict PASS / FAIL / UNKNOWN. This is how we flag a protection the optimizer silently removed — the failure mode a source-only review can never see.
Why this step needs AI
Cross-checking countermeasures against the disassembly is, in principle, something a firmware engineer can do by hand. In practice it’s brutally tedious. A 16 KB ROM built with -Os -flto disassembles into thousands of lines where inlining, instruction reordering, and register reuse have scrambled any tidy relationship to the source. To confirm a single countermeasure survived, an engineer has to find the right code region, mentally reconstruct what the optimizer did, and decide whether the logic is genuinely present or an accidental look-alike, then repeat that well over a hundred times, staying as sharp on the last one as the first.
That’s the kind of work where even skilled engineers can slip: it’s tedious, repetitive, and unforgiving of a single lapse in attention. Miss one silently-removed check and a real protection is absent from shipped silicon. An AI-assisted flow reduces that effort tremendously — the model does the exhaustive line-by-line reading and hands the engineer a ranked list of what to look at and why, turning days of human error-prone scanning into focused review of the handful of findings that actually need judgment.
A worked example: from inventory entry to verdict
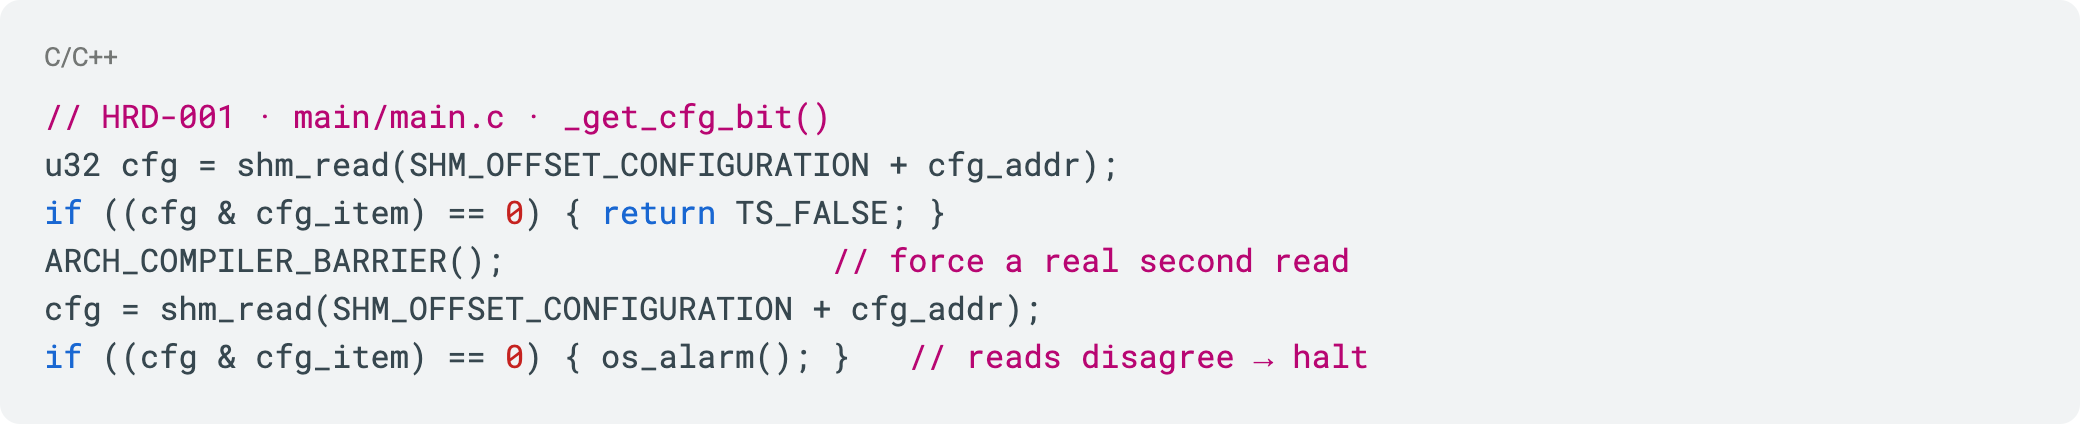
Step 1: The inventory captures the countermeasure (input). The hardening-inventory skill records each countermeasure with its exact location and code. For instance, a double-read of the chip’s configuration that alarms if the two reads disagree — a classic defense against a glitch corrupting a single read:
Step 2: The cross-check confirms it survived compilation (verdict). The hardening-cross-check skill locates that same logic in the disassembly and returns:

Both reads and the mismatch-alarm are present in the binary — the countermeasure is real on silicon.
But not everything survives. The same run flags a bounds assertion on an OTP config read that the optimizer removed:

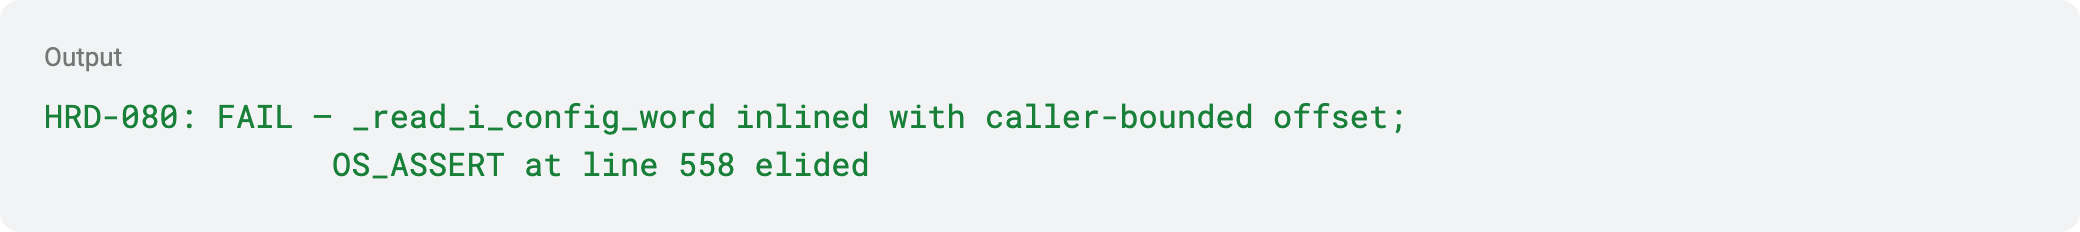
The assertion is gone from the binary — because the compiler inlined the function, saw that every caller already passes an in-range offset, and proved the check could never fire. That’s exactly the source-vs-binary gap this step exists to catch.
These are assistive, supporting steps — not the verdict. A FAIL is a flag for an engineer, not an automatic bug. Often the elision is benign, as here: the compiler removed a check it could guarantee was never needed. The AI reads at a scale and consistency people can’t, and points precisely at what to inspect, but a firmware engineer makes the call on whether a finding matters, and owns the sign-off.
How often we use AI models
We run AI models on every bootloader release candidate, verification is a release gate, not a one-time experiment. On models, our rule of thumb is simple: baseline with a strong, stable model, then see if a newer one does better. What we’re finding matches our intuition. The open-ended static analysis is where a more capable model earns its keep, while the cross-check against the disassembly is a defined task where a steady baseline and consistency matter more than raw creativity.
Five things we’d tell another team trying this
- Put the AI in the repo, not in a chat window. Version-controlled skills pinned to a commit are the difference between a reproducible verification gate and an anecdote.
- Check against the artifact that actually ships. Source-level review is necessary but not sufficient; the binary is the source of truth.
- Give the model a false-positive memory. A curated list of known-benign patterns is what turns a noisy tool into a usable one.
- Match the model to the task. Spend your most capable model on open-ended analysis; a steady baseline is fine for mechanical cross-checking.
- Keep the human as decision-maker. AI reads at a scale and consistency people can’t, but, sign-off and accountability stay with the engineer.
The takeaway: open and auditable isn’t just good for trust. It lets us point frontier AI straight at the bootloader in our firmware and make thorough, repeatable verification a standing part of every release.